How AIR Runs AI SOC Investigations
Most debates about AI in the SOC collapse into a false binary.
On one side is the old automation model: deterministic workflows, rigid playbooks, predefined steps, and brittle logic. On the other is the AI-native promise: fully agentic investigations where an AI system adapts freely based on whatever it learns along the way.
That framing is too simple.
Deterministic does not have to mean rigid. Agentic does not automatically mean better. In production security operations, the goal is not to build the most open-ended investigation system possible. The goal is to produce accurate, consistent, explainable investigations at scale.
That requires architecture. At Daylight, AIR is the investigation engine behind our managed security services. It runs investigation templates through a central orchestrator and coordinates multiple specialized agents. AIR is used across alert investigations, threat hunting, and agentic data lake queries.
AIR does not treat every investigation as a blank page for an agent to reason through from scratch. It also does not reduce investigations to static SOAR-style playbooks. It combines deterministic and agentic workflows in the same investigation.
When the required data is clear and easy to retrieve, AIR uses deterministic flows. When the task requires reasoning, interpretation, or semantic understanding, AIR uses specialized agents.
That distinction is what makes the system reliable.
How an AIR investigation actually runs
Every AIR investigation starts with a raw event: an alert, detection, or trigger from a threat hunt that found a suspicious lead.
That event determines which investigation template should run. A template may apply broadly to several alerts from a specific integration, or it may be specific to a case type within that integration. When Daylight builds an integration, our security experts determine which investigation templates are needed and define how those investigations should be handled.
A template defines the required evidence collection, enrichment, analysis steps, expert guidelines, knowledge retrieval, and conditional workflows for that investigation type.
The investigation then follows a structured sequence.
First, AIR collects the data required for the investigation. This is the deterministic foundation. The template defines which telemetry and entities matter for that alert.
Next, AIR performs enrichment. It collects relevant information about indicators and entities such as users, devices, IP addresses, domains, files, cloud resources, SaaS applications, and other objects involved in the investigation.
Then AIR applies the expert guidelines defined in the template. These guidelines encode Daylight’s investigative logic into the process. They define how evidence should be interpreted, which conditions matter, what additional checks should run, and when specific agentic workflows should be activated.
For example, in an impossible travel investigation, experts may define thresholds for travel distance, speed, or timing. Activity below a certain threshold may be normal. Activity within a middle range may require additional validation. Activity above a defined threshold may be treated as highly suspicious or physically impossible. Rather than forcing AI to infer those judgments from scratch, the guidelines help AIR evaluate evidence consistently.
After that, AIR retrieves relevant knowledge items.
Daylight maintains customer-specific context repositories as part of the agentic platform. The Daylight Data Lake stores telemetry. Daylight Knowledge stores organizational and historical context.
Organizational context includes business rules, policy exceptions, asset ownership, user roles, sensitive systems, and customer-specific operating knowledge. Historical context includes prior investigations, recurring false-positive patterns, known behaviors, previous decisions, and lessons learned from earlier cases.
AIR runs a matching process to retrieve knowledge items relevant to the investigation. Organizational context is considered first, followed by historical context.
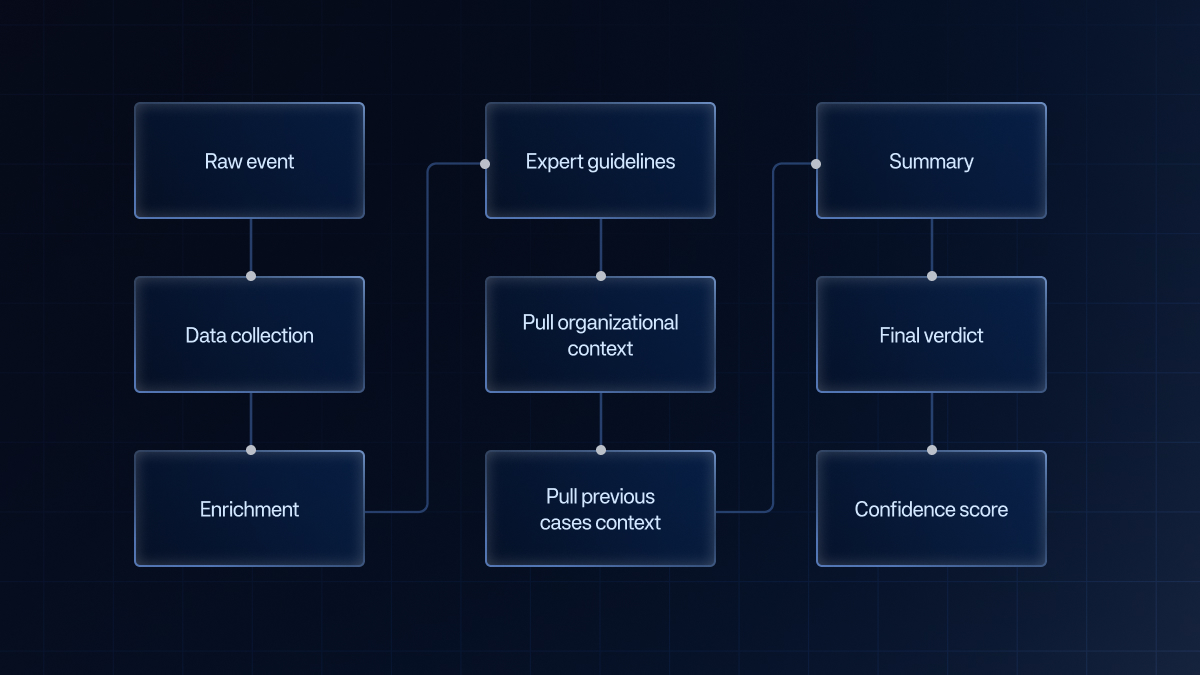
Once AIR has collected the required data, enrichment, expert guidelines, and relevant knowledge items, it generates a summary and then a final verdict. The verdict determines whether the activity is benign, false positive, suspicious or a true positive.
Deterministic does not mean static
Some parts of an investigation should not depend on agentic judgment.
If an investigation requires recent authentication history, the workflow should retrieve it. If it requires enrichment for an IP address, domain, file hash, user, device, cloud resource, or SaaS activity, the workflow should run the appropriate enrichment. If it needs logs from a known integration, the workflow should query the appropriate source.
There is no benefit in asking an AI agent to decide whether required evidence should be collected. If the evidence matters for that investigation type, the system should collect it consistently.
That is what deterministic means in this context.
It means the investigation has a reliable backbone. The same class of alert receives the same required evidence collection. The same enrichment logic runs. The same relevant sources are checked. The process is visible and repeatable.
That does not make the investigation less intelligent. It makes it more dependable.
Agentic workflows are used when reasoning is actually needed
Not every investigative task can be reduced to a simple API call.
Some tasks require interpretation: stitching together incomplete signals, understanding business context, or resolving entities that appear differently across systems. That is where AIR uses agents.
AIR includes a central orchestrator and multiple specialized agents. Each agent performs a specific investigative task, such as building a unified user profile, identifying the relevant machine for a user, finding a GitHub pull request connected to suspicious activity, analyzing browser history, or collecting context about a cloud resource, endpoint, SaaS application, or Kubernetes workload.
The orchestrator manages the investigation flow and decides which agents should run based on the investigation template and its conditions. Agents perform actions, retrieve information, analyze specific evidence, and return their output back into the investigation.
This matters because the unit of intelligence is narrow. A specialized agent is not asked to “investigate the alert.” It is asked to complete one defined task within the investigation.
These are good uses of agents because the work requires reasoning across messy or semantically complex data. But the agentic workflow still happens inside the structure of the investigation. It is activated because the template calls for it, or because a condition in the template is met. It is not open-ended exploration for its own sake.
Conditions make investigations adaptive without making them unpredictable
A common misconception is that an investigation is either static or fully agentic.
In practice, the stronger model is a combination of both.
AIR investigation templates can include conditions. A condition defines when additional work should happen. If specific evidence appears, if required context is missing, or if a certain risk pattern emerges, the investigation can activate an additional agentic workflow.
For example, an investigation may start with deterministic data collection and enrichment. It may retrieve authentication activity, identity context, endpoint telemetry, cloud activity, and relevant indicators. Then a condition may be met: the user context is unclear, the activity involves a sensitive system, the machine identity is ambiguous, or the business justification cannot be determined from structured telemetry alone.
At that point, AIR can run an agentic workflow to gather richer context.
That may mean building a more complete user profile, finding the user’s associated machine, reviewing browser activity, identifying a relevant GitHub pull request, or collecting additional cloud or Kubernetes context to understand what the asset is and why the activity happened.
This is not a static investigation. The path changes based on what the investigation finds.
But it is also not a fully agentic investigation workflow where the system invents the process as it goes. The adaptation happens through conditions that were designed as part of the investigation template.
That structure is important for reliability. It lets the system adapt without becoming inconsistent, opaque, or difficult to improve.
Fully agentic investigations can reduce consistency and accuracy at scale
A fully agentic investigation workflow is appealing in theory.
An alert fires. An AI agent reviews the evidence. It decides what to check next, pivots across systems, and adapts dynamically until it reaches a conclusion.
That resembles how experienced analysts investigate difficult cases. They follow leads, change direction, notice gaps, and decide when a different question matters more.
But production investigations cannot depend entirely on open-ended reasoning. For many alert types, there is a known set of evidence that should be collected every time. A suspicious login investigation should not depend on whether an agent decides that authentication history, MFA activity, device context, user role, or prior similar cases are worth checking. If that evidence matters, it should be collected consistently.
When every investigation path is decided dynamically, two investigations for the same alert type can collect different evidence, follow different branches, and weigh different signals. At small scale, that variability can look like flexibility. At production scale, it becomes a reliability problem.
It also creates an accuracy problem.
Security investigations are not just reasoning exercises. They are evidence-gathering processes. If the system skips a required source, stops too early, follows an irrelevant branch, or over-weights a weak signal, the final verdict can be wrong even if the reasoning sounds plausible.
This is especially important in enterprise environments, where a single alert often requires telemetry context, organizational context, and historical context to interpret correctly. The investigation needs to know which evidence is mandatory, which context matters, and which questions must be answered before a verdict can be trusted.
Explainability is part of the issue, but it is not the whole issue.
A SOC cannot rely on investigations that are difficult to audit, difficult to reproduce, difficult to improve, or inconsistent across similar cases. The point is not whether AI can sometimes reach the right answer. The point is whether the investigation process can produce accurate, repeatable results at scale.
That is why Daylight does not assume that more agentic is always better.
Confidence is not just a feeling
In security operations, a verdict is not enough.
The system also needs to know how confident it should be in that verdict. A low-confidence benign verdict is very different from a high-confidence benign verdict. A true positive with incomplete evidence should be handled differently from a true positive supported by clear telemetry, relevant context, and consistent historical patterns.
AIR handles this by structuring the final evaluation around analyst questions.
For each investigation, AIR generates several questions that need to be answered to evaluate the investigation and the verdict. These questions depend on the investigation type and the evidence collected. The LLM assigns a factor to each question based on its importance to the investigation. Those factors contribute to the confidence score.
The purpose is to avoid treating confidence as a vague model-generated sentiment. AIR breaks the investigation into specific questions, evaluates the available evidence, and uses that structure to determine whether the verdict is reliable enough.
That experts may decide more data is needed. They may request a pivot after the verdict. They may decide the investigation needs a different approach. They may update investigation templates if the issue reflects a gap in the process. They may create or update knowledge items so similar future cases are handled with better context.
This is how the system improves.
Human experts improve the investigation architecture
The role of Daylight’s security experts is not limited to reviewing AI output.
They design investigation templates when integrations are built. They define required data collection. They determine which enrichment matters for each case type. They write the guidelines that shape the investigation. They identify where agentic workflows are useful and where deterministic steps are better.
They also review low-confidence investigations, tune templates when there are issues, create and update knowledge items, and request pivots after verdicts when more information or a different investigative direction is needed.
In Daylight’s model, the expert’s highest-leverage work is improving the investigation architecture itself.
If a low-confidence investigation reveals a missing context item, that context can be added to Daylight Knowledge. If a template repeatedly fails to collect the right evidence, the template can be changed. If an agentic workflow is producing inconsistent output, the workflow can be inspected and improved. If experts repeatedly request the same pivot after a certain verdict, that learning can become part of the future investigation process.
The system becomes more accurate because expert judgment is not trapped inside individual tickets. It is encoded back into the investigation architecture.
The real question is not deterministic or agentic
The AI SOC market often frames the conversation as a choice between deterministic automation and agentic investigation.
That is the wrong question.
The real question is whether the investigation architecture can produce professional, high-confidence, accurate investigations at scale.
To do that, the system needs structure. It needs to know which evidence is required for each case type. It needs to retrieve only the context that matters. It needs to use agents for tasks that require reasoning, not for every step indiscriminately. It needs to make the investigation path visible. It needs to know when confidence is low. And it needs security experts who can improve the system when gaps appear.
That is how Daylight built AIR.
Not as a static playbook engine. Not as a fully agentic black box.
As an investigation engine that combines deterministic and agentic workflows in the places where each one works best.
That architecture is what makes AI investigations more consistent, more accurate, more explainable, and more reliable in production security operations.
Subscribe to newsletter
Subscribe to receive the latest blog posts to your inbox every week.
Related posts
For expert judgment, scaled to your world, head for Daylight
